Most security practices are built on a simple assumption: the threat comes from outside. You monitor the connection between your machine and a server, and you filter what comes in. Multi-agent systems move the problem somewhere that assumption no longer holds. Here, the risk arises not in the external connection, but in the internal conversation between agents programmed to trust one another.
This article explains what a multi-agent system is, how an attack called Prompt-Chain Hijacking spreads through the chain, why conventional security tools fail to detect it, what Zero-Trust orchestration involves, and where the chain can actually be broken. As in the rest of this series, the limits of each defense are described directly, without exaggeration.
The promise that "collaborative" intelligence fails to keep
To automate complex workflows, many organizations have moved from standalone chatbots to multi-agent systems (MAS). These are environments in which specialized agents work together: one searches the web, another summarizes documents, and a third executes code.
The design principle is sound. Breaking a task into small, modular stages makes the system more predictable and more capable. Each stage does one thing and passes the result along.
But this division creates what could be called a trust cascade. In a multi-agent environment, agents are designed to treat input from their peers as verified fact. That implicit trust is not a flaw; it is what allows the system to operate smoothly. It is also the system's greatest structural weakness, exploited through an attack method called Prompt-Chain Hijacking.
How a hijack spreads
In a single-agent system, a malicious prompt—often called a "prompt injection"—attempts to trick the AI into ignoring its instructions. In a multi-agent system, the same attack is far more dangerous because it can propagate.
Imagine an automated content pipeline with three stages:
- Agent A (the scout) searches the web for research.
- Agent B (the writer) summarizes that research into a draft.
- Agent C (the reviewer) checks the draft for compliance.
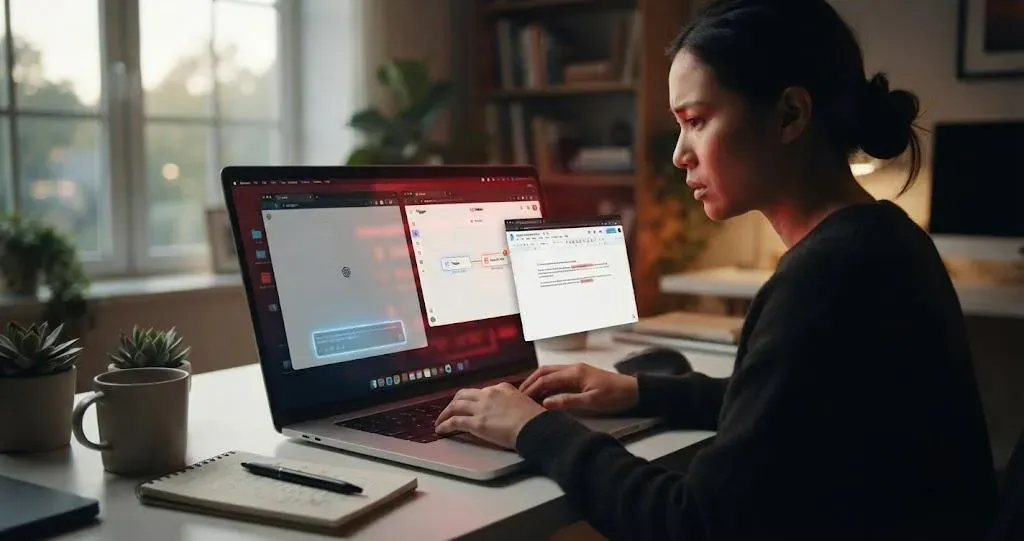
If an attacker can hide a malicious instruction on a single web page visited by Agent A, the damage does not stop with Agent A. The instruction poisons the context window passed to Agent B. By the time Agent C receives the "summarized" document, the harmful instructions are embedded in the text as if they were legitimate data.
The key point is that none of the later agents detects anything unusual. They treat input from a peer as true, exactly as they were designed to. The attacker has hijacked the entire chain, often without the user ever seeing a single suspicious line.
The attacker has hijacked the entire chain, often without the user ever seeing a single suspicious line.
Why your security framework is blind
Most enterprise security tools are built for the client-server model. They monitor the connection between your computer and the AI's central server. What happens inside the system once that connection is established lies outside their field of view.
Multi-agent systems exchange data through fast, internal agent-to-agent communication protocols. These "lateral" movements are rarely logged or audited. That leaves three specific blind spots worth understanding rather than taking for granted.
| Blind spot | What happens | Why it is dangerous |
|---|---|---|
| Context contamination | A compromised agent writes distorted information into shared memory | Each subsequent agent assumes the data is valid, allowing the error to spread laterally one stage at a time |
| Control-flow hijacking | Metadata or the instruction flow itself is manipulated between agents | Agent A is forced to trigger an unwanted "tool call"—such as an API request—that the developer never intended |
| The trust gap | Models are more likely to follow malicious instructions from a "peer agent" than from a human | The system is designed to relax its own safety checks to enable seamless collaboration |
The pattern is the same as in earlier articles in this series: the tools are not broken. They are simply guarding a door the attack does not use.
The path to Zero-Trust orchestration
The era of "plug-and-play" agent integration is over. Securing a multi-agent pipeline requires a shift to Zero-Trust orchestration. In short, every message sent between agents must be treated with the same skepticism as a raw request from the internet.
That means abandoning the built-in assumption that a peer agent is trustworthy. No internal message is accepted as truth simply because it comes from another stage in the chain. Everything must be checked, every time.
This is where Total Adblock applies what is known as pipeline-level sanitization. Instead of blocking only in the browser, it analyzes the data flowing between your agents. By inspecting internal communications, it identifies context contamination—when an agent attempts to pass injected instructions or unauthorized API calls to its peers. The logic follows a direct chain:
- Every internal message is treated as a potential attack vector, not as verified data.
- If a message contains an injected instruction or an unauthorized tool call, the connection is interrupted before the message reaches the next agent.
- If the message never arrives, one compromised agent cannot spread the error through the rest of the workflow.
This limitation deserves the same honesty as in previous articles. Pipeline-level sanitization catches propagation going forward; it does not rewrite shared memory already poisoned during an earlier run, nor does it change how a closed third-party platform handles data internally. Its job is to close the path ahead—which, against an attack that survives by spreading from stage to stage, is precisely the path that matters. Because the filtering targets abnormal forwarding rather than legitimate messages, the agent collaboration you have approved can continue to function.
Take back control of your automated workflow
What is unsettling about multi-agent systems is not that they are advanced. It is that the very quality that makes them useful—the agents' ability to trust one another and build on each other's work—is the same quality an attacker exploits. Productivity and vulnerability are two sides of the same design.
The practical response is not to abandon automation or treat every agent as an enemy. It is to stop viewing your AI assistants as neutral tools. They are powerful data processors with access to your internal systems, and without clear boundaries between stages, they may automate their own compromise. The goal is simple: determine what each stage may pass along and interrupt any forwarding you never approved.
Do not let a chain reaction spread through your entire infrastructure because one stage was tricked. Protect your AI pipeline with Total Adblock.